Movie Recommendation
A production-grade semantic search engine that recommends movies based on thematic meaning rather than basic keyword matching.
Overview
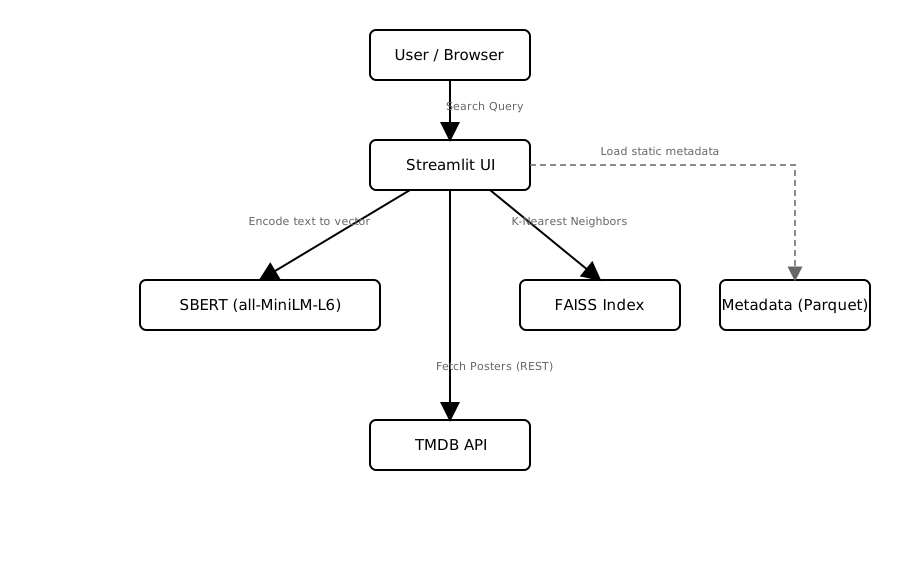
Most movie recommenders rely on simple keyword matching or collaborative filtering, which often misses the actual context of a film. I built this system to understand the thematic meaning of a movie. It acts as a semantic search engine using SBERT (Sentence-BERT) to understand the user's input context, and retrieves visually rich, real-time movie data via the TMDB API.
What I Did
I engineered the complete ML pipeline, from data preprocessing with Pandas to generating text embeddings using the `all-MiniLM-L6-v2` model. I integrated FAISS (Facebook AI Similarity Search) to handle high-speed vector retrieval. For the frontend, I built a custom monochromatic 'Obsidian' themed UI using Streamlit and packaged the entire application in a Docker container for easy deployment.
Tech Stack
Technical Decisions
I chose SBERT (`all-MiniLM-L6-v2`) because it provides an excellent balance between embedding quality and inference speed, which is crucial for a real-time app. FAISS was used over a traditional database because it's heavily optimized for sub-millisecond vector similarity search. Streamlit allowed me to rapidly build a clean, functional UI purely in Python without dealing with a separate frontend framework.
Architecture
What I Learned
I learned how to work with dense vector embeddings and handle the complexity of vector similarity search at scale using FAISS. Dealing with PyTorch models taught me a lot about managing memory and inference speed. I also gained practical experience Dockerizing a full machine learning application so it runs consistently anywhere.